Components of Feature Engineering
A feature engineering pipeline consists of multiple components. The Data Source node is mandatory and loads the source dataset into the pipeline. The remaining nodes are optional and should be selected based on your use case, the characteristics of your dataset, and the desired outcome. This section describes the purpose of each node. For guidance on selecting the appropriate nodes for your pipeline, see How to Design Your FE Pipeline.
-
Data Source Nodes - These components load the source dataset into the FE pipeline.
 Database Table
This component loads the source dataset into the Feature Engineering (FE) pipeline in the form of tables.
To add and configure a database table, do the following:
-
Drag and drop the Database table node. This is the source node for your FE pipeline. This is a mandatory node.
-
Click the node to configure it.
-
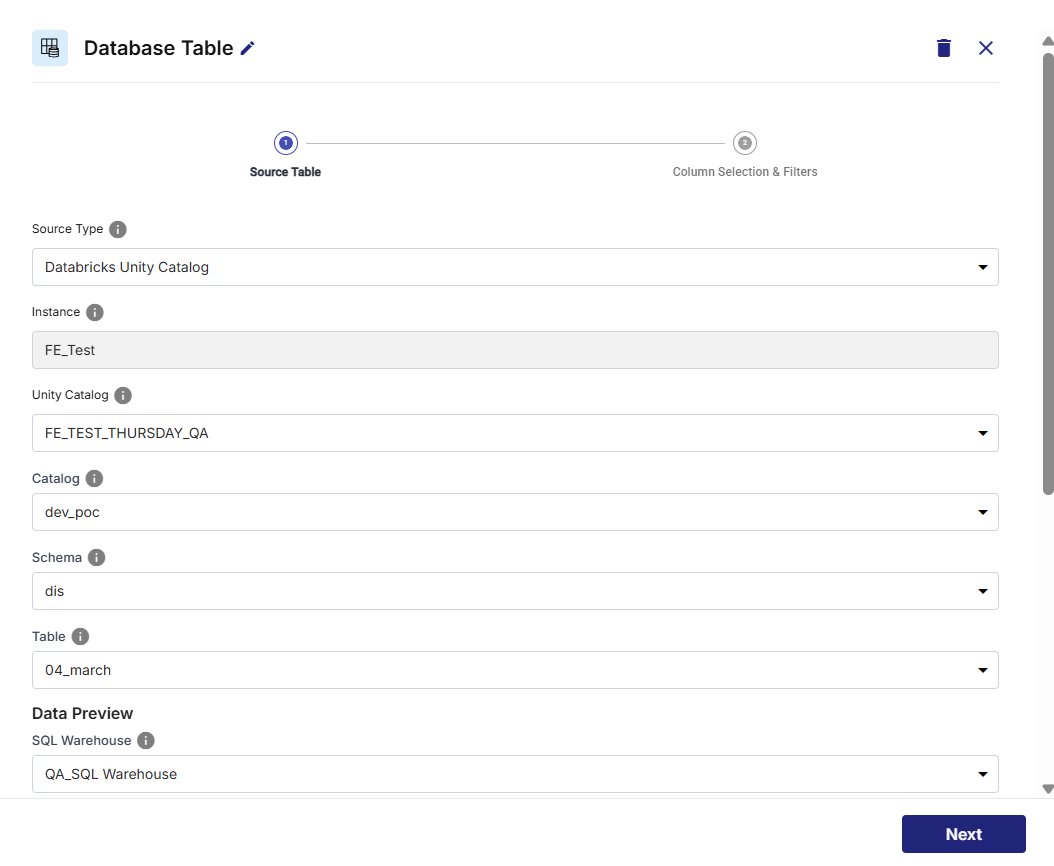
On the Source Table step, do the following:
-
Source Type – By default, Databricks Unity Catalog is selected, and you cannot edit it.
-
The Databricks instance is pre-populated.
-
The Unity Catalog associated with the Databricks instance is selected.
-
Select the catalog and schema.
-
Select a table. The SQL warehouse that is available is auto selected. You can view the Data Preview.
-
Click Next.
-
-
On the Column Selection and Filters step, do the following:
-
The Selected Table name is displayed.
-
By default, all the columns are selected from the table. You can deselect the columns that you do not require.
-
Use Filters to filter specific records from the dataset. Specify the column, operator and value for the filter. Click Apply.
-
You can view the Data Preview, based on the column selection and applied filers.
-
Click Configure. A success message is displayed; this confirms that the source node is configured.
-
-
Feature Engineering Nodes - These components of the FE pipeline include various techniques to transform data into features.
Data Cleaning
Data cleaning is the process of identifying, correcting, and removing issues in raw data like handling missing or null values, removing duplicate records, or correcting inconsistent data formats. There are several data cleaning methods that can be used as follows:
-
Dedup - Removes duplicate rows or records from the dataset to avoid redundant data.
-
Key Columns - Select the columns from which you want to remove duplicate records.
-
-
Drop Columns - Removes selected columns that are irrelevant, sensitive, or not useful.
-
Columns to Drop - Select the columns to drop from the dataset.
-
-
Drop ID-like Columns - Removes columns that contain unique identifiers such as IDs, UUIDs, email IDs, or transaction numbers that usually do not contribute meaningful predictive values.
-
Columns to Drop – Select the columns to drop from the dataset.
-
Threshold – Specify the minimum uniqueness percentage required to classify a column as ID-like.
-
Approx Distinct - This is an approximate calculation of the number of unique values in a column.
-
-
Drop Low Variance Columns - Removes columns where values change very little across records that typically provide minimal predictive information.
-
Columns to Drop – Select the columns to be dropped for this method of data cleaning.
-
Threshold – Enter the minimum variance required for a column to be retained. Columns with a variance below this value are considered low-variance features and are dropped from the dataset.
-
-
Drop High Missing Columns - Removes columns that contain a large percentage of missing (null) values.
-
Columns to Evaluate – Select the columns to be checked for missing values.
-
Missing Value Threshold – Specify the missing value percentage threshold. Columns with missing values equal to or above this threshold are removed from the dataset.
-
-
Null Normalization - Converts different representations of missing values into a standard null value for consistent data processing and analysis.
-
Columns – Select the columns on which null normalization is to be implemented.
-
Null Types – Select the null representations that are to be replaced with the default null representation.
-
Trim – Trims the surrounding whitespace before matching the selected null types.
-
Imputation
Imputation is the process of replacing missing values with substitute values so that ML models can be trained to make predictions without loss of information. Many ML algorithms cannot handle null or missing values directly. There are several methods of imputation that include:
-
Mean - Replaces missing value with average value of the column.
-
Columns – Select the columns in which you want to replace missing values.
-
Add Missing Indicator – Adds an additional column that acts as a flag to indicate that the original value was missing and is replaced.
-
-
Median - Replaces missing value with median value. This method is appropriate when data contains outliers.
-
Columns – Select the columns in which you want to replace missing values.
-
Add Missing Indicator – Adds an additional column that acts as a flag to indicate that the original value was missing and is replaced.
-
-
Mode - Replaces missing value with most frequent value.
-
Columns – Select the columns in which you want to replace missing values.
-
Add Missing Indicator – Adds an additional column that acts as a flag to indicate that the original value was missing and is replaced.
-
-
Missing Label - Replaces missing value with a dedicated new category such as Missing or Unknown.
-
Columns – Select the columns in which you want to replace missing values.
-
Add Missing Indicator – Adds an additional column that acts as a flag to indicate that the original value was missing and is replaced.
-
-
Constant – Replaces missing value with a constant value.
-
Constant Values - Select the column in which you want to replace missing values.
-
Enter the value to be replaced.
-
-
Forward Fill - Replaces missing value with the most recent non-null value that appears before that row in the dataset.
-
Columns to Fill – Select the columns in which you want to use this method to replace missing values.
-
Order By – Specifies the column used to determine the sequence of records when performing forward fill.
-
Group By - Specifies one or more columns that partition the data into separate groups before applying forward fill.
-
Sort Direction – Specifies the direction in which the data is sorted – ascending or descending.
-
Max Consecutive Fill – Specifies the maximum number of records that can be replaced with this method.
-
Fallback Imputation – The value to be used to replace the missing value in case the selected method cannot be implemented.
Consider the following example of sensor temperature readings collected every hour:
Time
Temperature (degree Celsius)
9:00
22
10:00
23
11:00
Missing
12:00
Missing
1:00
25
2:00
Missing
-
When you apply the forward fill method on this data, it will be filled with the following values:
|
Time |
Temperature (degree Celsius) |
|---|---|
|
9:00 |
22 |
|
10:00 |
23 |
|
11:00 |
23 |
|
12:00 |
23 |
|
1:00 |
25 |
|
2:00 |
25 |
-
Backward Fill - Replaces the missing value with the next available non-missing value in the dataset.
-
Columns to Fill – Select the columns in which you want to use this method to replace missing values.
-
Oder By – Specifies the column used to determine the sequence of records when performing forward fill.
-
Group By - Specifies one or more columns that partition the data into separate groups before applying forward fill.
-
Sort Direction – Specifies the direction in which the data is sorted – ascending or descending.
-
Max Consecutive Fill – Specifies the maximum number of records that can be replaced with this method.
-
Fallback Imputation – The value to be used to replace the missing value in case the selected method cannot be implemented.
Consider the following example of product prices:
Date
Price ($)
Jan 1
100
Jan 2
Missing
Jan 3
Missing
Jan 4
105
Jan 5
Missing
Jan 6
110
-
After applying backward fill, the table is populated with the following values:
|
Date |
Price ($) |
|---|---|
|
Jan 1 |
100 |
|
Jan 2 |
105 |
|
Jan 3 |
105 |
|
Jan 4 |
105 |
|
Jan 5 |
110 |
|
Jan 6 |
110 |
Encoding
Encoding is the process of converting non-numerical categorical data into numerical values so that ML algorithms can process the data. Since most ML models only work with numerical data, encoding is an essential preprocessing step.
The various encoding methods are as follows:
-
One Hot Encoding - Creates a separate binary column for each category. This method can be used for categories with no inherent order like country or color.
-
Columns – Select the columns to apply one hot encoding method.
-
Maximum Categories – Specify the maximum number of categories to encode.
-
-
Ordinal – Assigns numeric values to ordered categories. For example, Poor, Fair, Good, and Excellent.
-
Ordinal Orders – Select the column and provide the ordinal order to be applied.
-
Provide the value.
-
-
Frequency - Replaces each category with the number of times it appears in the dataset. Useful for high cardinality features, where frequency carries information. For example, City: New York (300), Chicago (500).
-
Columns – Select the columns to which you want to apply this technique.
-
Value Type – Select proportion or count. Proportion calculates the percentage, while count provides the actual number of times the data appears in the column.
-
Output Suffix – Provide the suffix that is to be applied for the column.
-
-
Rare Category Encoding - Groups infrequently occurring categories into a single common category, such as "Other" or "Rare". Datasets often contain many unique values, many of which appear only a handful of times. Such values introduce noise and lead to poor model performance.
-
Columns – Select the columns to apply Rare Category Encoding.
-
Rare Category Threshold Type – Select how rare categories are identified. Categories below the selected threshold are grouped as rare categories.
-
Minimum Count – Use this option to specify the minimum number of occurrences.
-
Minimum Frequency – Use this option to specify the minimum percentage of records required for a category to be retained.
-
Specify the threshold value used to identify rare categories. Categories with a count or frequency below this value are grouped as rare.
-
-
Rare Label – Specify the label assigned to all categories identified as rare, such as Other or Unknown.
-
Max Categories – Specify the maximum number of categories to retain after encoding. If the number of unique categories exceeds this limit, the least frequent categories are grouped as rare.
Example: The Payment Method column may have options like Credit Card, Debit Card, UPI, Net Banking, Gift Card, Cryptocurrency. Of these options gift card and cryptocurrency may have just a few occurrences in the dataset. These may be encoded as Others.
-
Imbalance Handling
Imbalance handling is the technique used to address class imbalance and prevent ML models from becoming biased toward an overrepresented majority. The absence of this technique can result in predictions becoming biased towards the majority (frequent) class.
The various methods of imbalance handling are as follows:
-
Class Weights - This method assigns higher weightage to minority-class samples during model training.
-
Target Column – Select the column to apply the class weights technique.
-
Weight Column - Specify the name of the column that stores the calculated class weight for each record. This column can be used during model training to assign higher importance to minority classes and lower importance to majority classes.
-
-
Custom Class Weights – This method assigns user-defined weights to different classes in a dataset. The model gives more importance to classes with higher weights during training.
-
Target Column – Select the column to apply custom class weight technique.
-
Weight Column – Specify the name of the column that stores the calculated class weight for each record.
-
Class Weight Map – Specify the weight to assign to each class value in the selected column. Select the class value.
-
Provide the weight to assign to the class value.
-
-
Oversample – This method increases the minority class samples to create a balanced dataset. This enables ML models to learn and predict underrepresented classes in a better way.
-
Target Column – Select the column to apply oversampling technique.
-
Max Multiplier – Provide the maximum number of times a minority-class row can be duplicated during oversampling.
-
-
Undersample – This method reduces the number of samples in the majority class to create a more balanced dataset. It removes some majority class records so that the model learns from a dataset where both classes are evenly represented.
-
Target Column – Select the column to apply undersampling technique.
-
Sampling Strategy - Specify the desired ratio of minority to majority samples after undersampling. This determines how many majority class records are retained.
-
Scaling
Scaling transforms numerical features to a common range or distribution, ensuring that features with larger values do not disproportionately influence machine learning models.
The various methods of scaling are as follows:
-
Standard - This method scales numeric features to a standard deviation of 1 while preserving their original mean.
-
Columns – Select the columns to apply the standard method of scaling.
Example:
Age (before applying scaling)
Age (after applying scaling) 20
-1.41
25
-0.71
30
0
35
0.71
40
1.41
-
-
MinMax - This method rescales values to a fixed range, usually 0 to 1. Here the smallest value becomes 0 and the largest value becomes 1, all other values fall proportionally between them.
-
Columns - Select the columns to apply the standard method of scaling.
Example:
Original Values
Modified Values 30000
0 45000
0.3 60000
0.6 80000
1 -
-
Robust – This technique transforms numerical features using the median and interquartile range (IQR). Since it is based on statistics that are less affected by extreme values, this method is particularly effective for datasets containing outliers.
-
Columns - Select the columns to apply the standard method of scaling.
-
-
MaxAbs - This technique divides every value by the largest absolute value in the dataset. It scales all values into the range -1 to 1 while preserving zeros and the sparsity of the data.
-
Columns - Select the columns to apply the standard method of scaling.
Example:
Original Values
Modified Values -80
-1 -40
-0.5 0
0 20
0.25 80
1 -
Feature Creation
Feature Creation creates new features from existing data using mathematical transformations, feature interactions, aggregations, date and time extraction, or domain-specific logic. The newly created features provide additional information that helps ML models identify patterns and make predictions.
The various feature creation methods are as follows:
-
Ratio – This technique creates a new feature by dividing one numerical feature by another to represent their relative relationship. This is useful for comparing values that are more meaningful as proportions than absolute numbers.
Example - Debt = ₹50,000, Income = ₹500,000. So, Debt-to-Income Ratio = 0.10
-
Feature Name – Specify the name of the output column that will store the calculated ratio.
-
Numerator Column – Select the column that is used as numerator to calculate the ratio.
-
Denominator Column - Select the column that is used as denominator to calculate the ratio.
-
Display as Percentage – Enable this option if you want to present the ratio as a percentage instead of a decimal value.
-
-
Difference Feature – This technique creates a new feature by subtracting one feature from another to measure the difference or change between two values.
Example - Revenue = ₹120,000, Cost = ₹80,000. So, Profit = ₹40,000
-
Feature Name – Specify the name of the column that stores the calculated feature.
-
Left Column – The column from which the subtraction operation is performed.
-
Right Column – The column which is subtracted from the left column.
-
-
DateTime Extraction – This technique creates new features by extracting components from a date or timestamp, such as year, month, day, hour, weekday, or quarter. These derived features identify seasonal or time-based patterns.
Example - Order Date: 2026-08-15 14:30. So, Year = 2026, Month = August, Weekday = Saturday, Hour = 14
-
Source Date Column – Select the source datetime column.
-
Extract Components – Select one or more datetime components to extract from the source date column. A new feature is created for each selected component.
-
Preview – Displays the names of the features that will be created based on the selected datetime components.
-
-
Interaction Feature – This technique creates a new feature by combining two or more existing features to capture relationships or interactions between them. Interaction features often reveal patterns that individual features cannot represent.
Example - Price = ₹500, Quantity = 4. So, Total Sales = ₹2,000
-
Feature Name – Provide a name for the new column that stores the calculated feature.
-
Select Columns – Select the columns to combine to create the new feature.
-
Preview – Displays the names of the feature and the columns combined to create it.
-
-
Polynomial Feature – This technique creates new numerical features by generating polynomial and interaction terms from existing numerical features.. This enables models to learn non-linear relationships between variables.
Example - x = 5. So, x² = 25, x³ = 125
-
Feature Prefix - Specify the prefix to add to the newly created feature. If not specified, the prefix poly_ is used.
-
Select Numeric Columns - Select one or more numeric columns to generate polynomial feature.
-
Degree - Enter a degree to use for polynomial transformation. Higher degrees create additional polynomial and interaction features, increasing feature complexity.
-
Maximum Generated Features - Specify the maximum number of polynomial features to generate. The number should be below 100.
-
-
Custom Feature – This technique creates a new feature using a user-defined formula, expression, or business rule based on one or more existing features. This allows domain-specific knowledge to be incorporated into the dataset.
Example - Age = Current Date − Date of Birth or Customer Value = Purchase Amount × Loyalty Score
-
Feature Name - Provide a name for the feature.
-
Expression - Provide an expression to create the feature.
-
Outlier Handling
Outlier Handling is a technique that identifies and treats unusually high or low data values (outliers) that vary significantly from the rest of the dataset.
The various methods of outlier handling are as follows:
-
Winsorization - is an outlier handling technique that replaces extreme values with predefined upper and lower threshold values instead of removing them. This reduces the influence of outliers while preserving all records in the dataset.
-
Columns – Select the columns to apply winsorization.
-
Lower Quantile – The percentile value that defines the lower threshold for identifying and treating extremely low values in a dataset.
-
Upper Quantile – The percentile value that defines that upper threshold for identifying and treating extremely high values in a dataset.
-
Relative Error - Specify the acceptable approximation error when calculating quantiles. Lower values produce more accurate quantile estimates but increase processing time, while higher values improve performance at the cost of accuracy.
Example
Original Salaries
Employee
Salary
A
35000
B
42000
C
50000
D
60000
E
500000
-
If the upper threshold is decided as 1,00,000, then after Winsorization, the salaries are:
|
Employee |
Salary |
|---|---|
|
A |
35000 |
|
B |
42000 |
|
C |
50000 |
|
D |
60000 |
|
E |
100000 |
-
Data Quality Nodes- This section lets you add components that perform data quality checks on the dataset. They help improve the quality and reliability of the dataset, before it is used for model training. These components identify and handle issues such as missing values, duplicate records, invalid data, and outliers to ensure that the data is clean, consistent, and suitable for feature engineering and machine learning tasks.
Data Profiling
Data Profiling is the process of analysing a dataset to understand its structure, quality, and statistical characteristics before applying feature engineering techniques. It identifies issues such as missing values, outliers, duplicate records, class imbalance, and feature distributions, enabling users to select the most appropriate preprocessing and feature engineering methods.
-
SQL Warehouse – Select a SQL warehouse to use for data profiling.
-
Target Column – Select the target columns to use for data profiling.
-
Profiler Constraints – Deselect the profiler constraints that you do not want to use.
-
Data Splitting Nodes - These components divide the prepared dataset into separate subsets, such as training, validation, and testing datasets. This enables unbiased model training, evaluation, and performance validation by ensuring that the model is tested on data that was not used during training.
Train/Test Split
Train/Test Split divides a dataset into separate training and testing subsets for ML training and testing. The training set is used to learn feature transformations and train the model, while the testing set is reserved for evaluating model performance on unseen data. This helps prevent data leakage and provides a reliable assessment of the model's ability to generalize.
The various methods of this technique are as follows:
-
Stratified – This method ensures that the class distribution of the target variable remains approximately the same in both the training and testing datasets. This prevents the minority class from being underrepresented and produces more reliable testing results.
-
Seed – Specify the random seed used to generate the data split. Using the same seed produces the same split across multiple runs.
-
Target Column – Select the target column used to preserve the class distribution when performing a stratified split.
-
Split Ratio - Specify the proportion of records to include in the training and test datasets. The remaining records are assigned to the test dataset while preserving the class distribution.
-
-
Manual – This method partitions the dataset into training and testing subsets using user-defined rules or predefined criteria, allowing complete control over how records are assigned.
-
Split Column - Select the column that contains the values used to manually assign records to the training and test datasets.
-
Manual Train Value - Specify the value in the selected split column that identifies records to include in the training dataset.
-
Manual Test Value - Specify the value in the selected split column that identifies records to include in the test dataset.
-
-
Chronological - Partitions the dataset according to the chronological order of records, using earlier observations for training and later observations for testing. This method is commonly used for time-series and forecasting applications.
-
Seed - Specify the random seed used to generate the data split. Using the same seed produces the same split across multiple runs.
-
Split Ratio – Use the slider to decide the ration in which to split the data.
-
Time Column – Select a date or time column to split the training and test data chronologically.
-
-
Random - Randomly partitions the dataset into training and testing subsets based on a specified split ratio, giving each record an equal probability of being assigned to either subset.
-
Seed – Specify the random seed used to generate the data split. Using the same seed produces the same split across multiple runs.
-
Split Ratio – Use the slider to decide the ratio in which to split the data.
-
Train/Validate/Test Split
Train/Validate/Test Split is a data preparation technique that divides a dataset into three subsets: training, validation, and testing. This approach enables ML models to be trained, tuned, and evaluated on separate datasets, reducing the risk of overfitting and providing a more reliable assessment of model performance.
The various methods of this technique are:
-
Stratified – This method ensures that the class distribution of the target variable remains approximately the same in both the training and testing datasets. This prevents the minority class from being underrepresented and produces more reliable testing results.
-
Seed– Specify the random seed used to generate the data split. Using the same seed produces the same split across multiple runs.
-
Target Column – Select the target column used to preserve the class distribution when performing a stratified split.
-
Split Ratio – Use the slider to decide the ratio in which to split the data into train, test, and validate.
-
-
Manual – This method partitions the dataset into training and testing subsets using user-defined rules or predefined criteria, allowing complete control over how records are assigned.
-
Split Column - Select the column that contains the values used to manually assign records to the training and test datasets.
-
Manual Train Value - Specify the value in the selected split column that identifies records to include in the training dataset.
-
Manual Test Value - Specify the value in the selected split column that identifies records to include in the test dataset.
-
Manual Validate Value – Specify the value in the selected split column that identifies the records to include in the validation dataset.
-
-
Chronological - Partitions the dataset according to the chronological order of records, using earlier observations for training and later observations for testing. This method is commonly used for time-series and forecasting applications.
-
Seed - Specify the random seed used to generate the data split. Using the same seed produces the same split across multiple runs.
-
Split Ratio – Use the slider to decide the ration in which to split the data.
-
Time Column – Select a date or time column to split the training and test data chronologically.
-
-
Random - Randomly partitions the dataset into training and testing subsets based on a specified split ratio, giving each record an equal probability of being assigned to either subset.
-
Output Nodes - These components store or publish the processed dataset after feature engineering is complete. The transformed data can be published to a feature store
Publish to Feature Store
This is a node that stores the engineered features as a managed feature table in Databricks Unity Catalog, making them available for use across ML models and pipelines.
-
Catalog – This is the catalog where the feature table will be created, this field is automatically populated.
-
Schema – This is the schema where the feature table will be created, this field is automatically populated.
-
Destination Table Name – Specify a name where the features are stored.
-
Description – Provide additional information related to the destination table.
-
Primary Key – Select one or more columns that uniquely identify each record in the feature table.
-
Version – Select auto-increment if you want to provide versions to the table. Else select none.
|
What's next?How to Design a Feature Engineering Pipeline |