Data Uniqueness
Overview
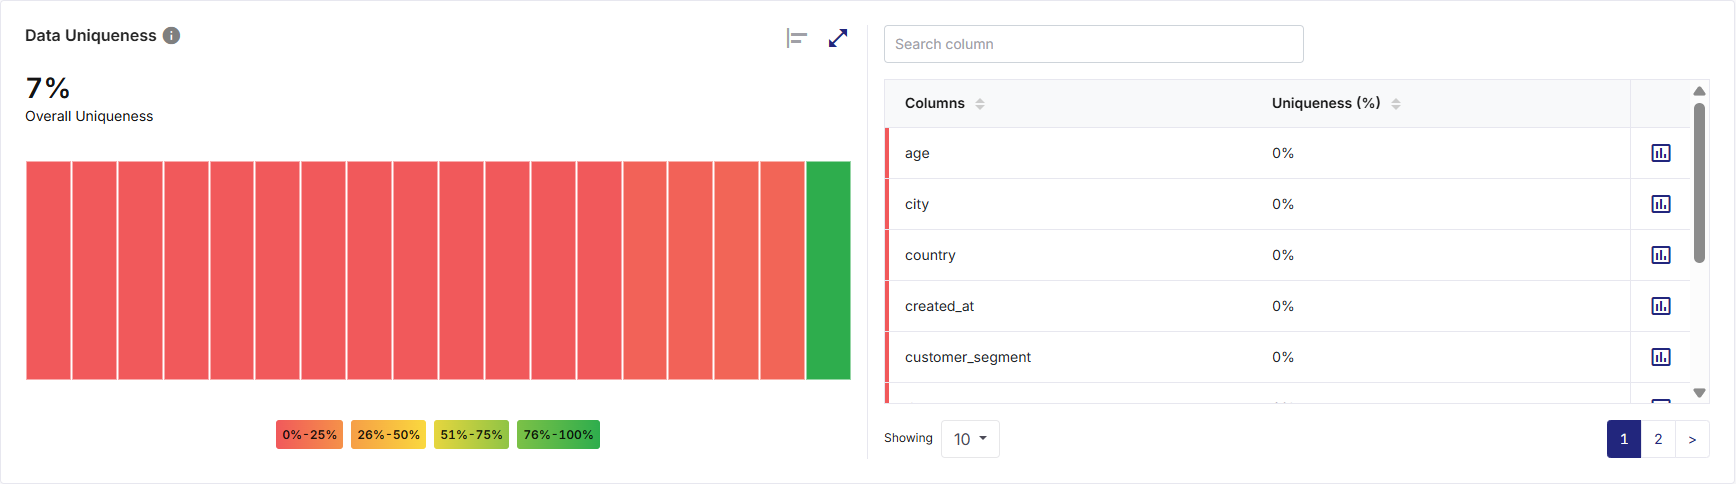
The Data Uniqueness widget provides insight into how unique the values are within each column of a dataset. It helps users quickly identify columns with high duplication, completely repeated values, or strong candidate keys by visualizing uniqueness percentages and overall uniqueness health across the dataset.
This widget supports data profiling to assess data quality, detect redundancy, and validate identifier columns. It provides a fast visual way to understand how distinct the data really is (both at the column level and across the dataset), making it a critical tool for early-stage data quality assessment.
What the Widget Analyzes
-
Profiling dimension: Data uniqueness
-
Level of analysis: Column-level with dataset-level aggregation
-
Calculation basis:
-
Uniqueness percentage for a column is calculated as:
(Number of distinct values / Total non-null values) × 100
-
Overall Uniqueness represents the aggregated uniqueness across all columns in the dataset, derived from individual column uniqueness values.
-
What the Widget Shows
-
Uniqueness percentage for each column in the dataset.
-
Visual comparison of uniqueness across columns using different chart views.
-
A dataset-level Overall Uniqueness score.
-
Color-coded uniqueness bands to indicate data quality ranges.
-
A supporting column list that displays exact uniqueness percentages for each column.
How to Read This Widget
-
Each visual element (point, bar, or block) represents a single column in the dataset.
-
The value of the element (line point, bar height, or tile) corresponds to the uniqueness percentage of a column.
-
Lower values indicate high duplication, and higher values indicate more distinct data.
-
Hovering over any visual element reveals a tooltip with the column name and exact uniqueness percentage or value.
Available Views
The widget supports multiple visualization formats in various chart or graph views on the left pane.
On the top right corner of the visualization pane, use the:
-
Chart or graph view icon to switch between available view types
-
Expand icon to visualize a larger view for detailed analysis
-
Collapse icon to restore the widget to its default size
Note:
Hover or click action on any chart/graph element reveals or highlights column-specific completeness values. All interactions are read-only and do not alter the dataset.
|
View Type |
Description |
|---|---|
|
Line / Area View |
This view displays uniqueness values as connected points and filled areas to show relative variation across columns. Useful for scanning overall patterns. |
|
Bar View |
This view displays individual bars for each column, making it easy to compare uniqueness percentages precisely. |
|
Summary (Overall) View |
This view displays a single Overall Uniqueness (%) value along with color-coded blocks representing quality ranges. |
Color Coding and Thresholds
Uniqueness values are visually grouped using color bands. These ranges help users quickly identify problematic or high-quality columns.
|
Range |
Interpretation |
|---|---|
|
0% - 25% (Red) |
Very low uniqueness, high duplication |
|
26% - 50% (Orange) |
Low uniqueness |
|
51% - 75% (Yellow) |
Moderate uniqueness |
|
76% - 100% (Green) |
High uniqueness, potential key column |
Supporting Panes
The widget includes a Data Uniqueness tabular summary pane on the right, always visible alongside the visualization pane on the left, providing detailed column-level context. It displays a list of all dataset columns along with their Uniqueness(%) values.
Pane Interactions
-
Provide a column name in the Search column list box filters columns in the table and quickly locates a specific column by name.
-
Click the download icon to export the result as PDF, CSV, or XLSX file. You can either download a consolidated file or individual widgets.
-
Download individual widgets to analyze specific visualizations in detail and gain deeper insights. Files are saved using a standard naming format by default, which you can rename locally after download:
<Data Profiler Results Widget name>_<Source Table name>.<pdf | csv | xlsx>
Example: DataUniqueness_bronzepatientvisitdetails.csv
-
For consolidated Excel downloads, each widget is exported to a separate worksheet. For example, three widgets are saved as three sheets within a single Excel file.
-
-
Click on the column headers to sort columns in ascending or descending order.
-
Click the chart icon for each column to open the data distribution (Uniqueness details for current vs. last 5 runs) view for that specific column. This enables a transition from summary level counts to value level distribution analysis.
-
Scroll to access the additional columns when the list exceeds visible space.
How to Interpret the Results
-
Columns with 0% uniqueness contain the same repeated value across all records.
-
Columns with low uniqueness may indicate categorical fields or data quality issues.
-
Columns with high uniqueness are strong candidates for identifiers or primary keys.
-
A low Overall Uniqueness score suggests widespread duplication across the dataset.
When to Use This Widget
-
To identify duplicate-heavy columns that may impact analytics.
-
To validate columns that uniquely identify each record in the data.
-
To assess dataset readiness for joins, aggregations, or deduplication rules.
-
To support downstream data quality rule creation (for example, uniqueness checks).
 Recommended Topics |
What's next? Character Count |